
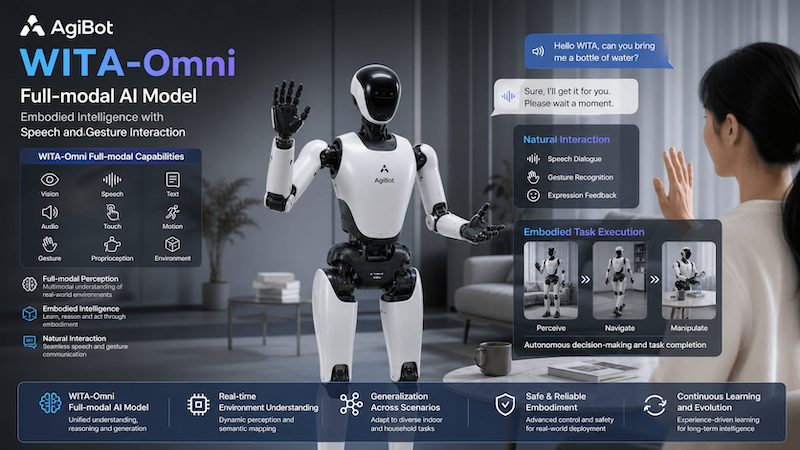
AGIBOT's WITA-Omni Preview multimodal foundation model has achieved the highest score on the Daily-Omni audio-visual reasoning benchmark, outperforming models from Alibaba, Google, and ByteDance. The model recorded an average accuracy of 85.21 percent, leading in audio-visual alignment, comparison, event sequencing, and both 30-second and 60-second video subsets. It ranked first or joint first in six of eight evaluation metrics, including tying for first in inference.
Key takeaways
- Daily-Omni benchmark evaluates real-world audio-visual reasoning with 684 videos and 1,197 questions across six task categories.
- WITA-Omni extends the Thinker-Talker framework with an Actor component, enabling coordinated movement and facial expressions as native outputs.
- The architecture integrates perception, reasoning, speech, and movement in a shared state, allowing robots to observe while responding.
- Trained on tens of millions of hours of multimodal data, with a three-stage process including supervised fine-tuning, on-policy distillation, and reinforcement learning using GRPO.
- Targets embodied AI applications, improving interaction decisions such as response timing and recipient selection.
For manufacturers, this advancement signals more context-aware human-robot collaboration, where robots can better interpret audio-visual cues and respond appropriately in dynamic environments. AGIBOT plans to integrate WITA-Omni into its robotic platforms, including humanoids and cleaning robots, to enable more natural interactions.
Source: Robotics & Automation News (roboticsandautomationnews.com) · Published 2026-08-03 · “AGIBOT’s foundation model tops benchmark test for audio-visual reasoning”